SurrealDB is a UK-based database company developing a unified, multi-model database that supports document, graph, relational, time-series, vector, search, geospatial, and key-value data. With SurrealDB (now at version 3.2), its Agent Memory layer, and next-generation storage layer (SurrealDS), the company is increasingly focused on providing memory, context, and data infrastructure for AI agents and enterprise AI applications. Pulse 2.0 interviewed SurrealDB Co-Founder and CEO Tobie Morgan Hitchcock to learn more.
Tobie Hitchcock’s Background
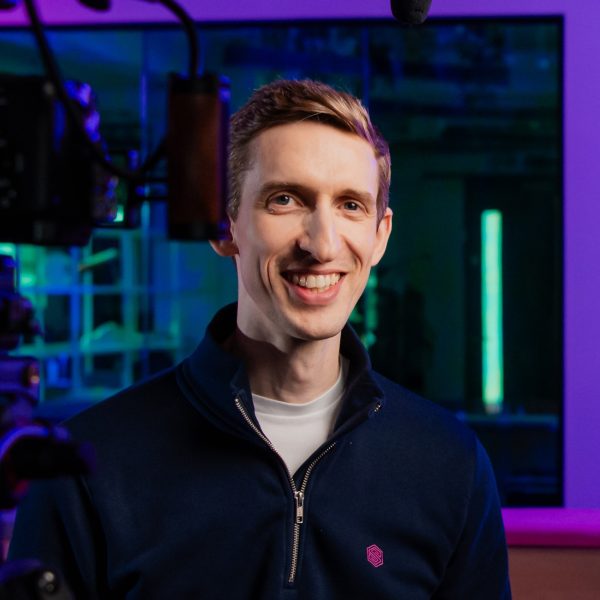
When asked about his background, Hitchcock shared:
My name is Tobie Morgan Hitchcock. I’m an Oxford-trained software engineer and co-founder of SurrealDB: a UK-based, VC-backed database startup. SurrealDB is a family-run business; I co-founded the company with my brother Jaime, and our mum Ingrid also works with us on the operations side.
I’ve always been obsessed with fixing broken systems. On a family holiday to Switzerland, when the hotel Wi-Fi didn’t work, I bought some tools and rewired the entire hotel network, something, I should add, I had permission to do. Our intolerance for badly designed, outdated, and overcomplex systems is what spurred the decision to create SurrealDB.
How SurrealDB Started
When asked how the idea for the company came together, Hitchcock explained:
The SurrealDB story started 10 years ago in the UK. Jaime and I were running a golf analytics startup where we juggled four separate databases: time-series, document, graph, and relational. It was a nightmare. We spent more time managing infrastructure than building the product.
So, we decided to build an entirely new kind of database, one unified system that could handle every data type and scale effortlessly. SurrealDB was the solution, and the company officially incorporated in 2021.
While SurrealDB grew out of a technical problem, how we built it has always been shaped by how we work together. I am the technical one and tend to approach things from a developer-first perspective, focusing on the underlying engineering, while Jaime leads on the commercial and operational side, with an instinct and eye for design.
We complement each other perfectly.
Ten years on, SurrealDB has become the fastest-growing database of all time. It has been downloaded over 4 million times, attracted over 33,000 GitHub stars, and has almost 1,500 forks.
Favorite Memory
When asked about his favorite memory working for the company so far, Hitchcock recalled:
It’s hard to pick just one moment. For me, it’s usually when we launch something new and see the positive response. No matter how many times we do it, the interest, enjoyment, and even surprise from developers are amazing. That’s what gives me the biggest buzz.
Core Products And Features
When asked about the company’s core products and features, Hitchcock detailed:
AI Agents need a unified view of state, combining semantic context, structured facts, and durable memory, but they struggle to remember facts consistently. They have difficulty understanding relationships and maintaining context as data size and complexity grow.
SurrealDB is designed to address this. It is the only database that enables first-class agent memory and contextual reasoning within the database. Models run alongside the data, context stays synchronized, and agent logic remains simpler as a result.
At its core, SurrealDB is a unified, multi-model database, supporting document, graph, relational, time-series, and vector data in a single engine with real-time capabilities built-in. SurrealDB 3.2 was recently released under General Availability (GA) as the most stable, performant, and enterprise-ready release of the database.
With this release, it moved SurrealDB beyond simply storing data, instead becoming the foundation for agent memory and intelligence.
A major innovation is the introduction of real-time contextual reasoning with Agent Memory and persistent object storage with SurrealDS. Rather than acting as middleware or a standalone vector store, Agent Memory is built directly into SurrealDB as a graph-powered, transactional memory layer for AI agents. SurrealDS provides persistent, large-scale data storage to support these systems.
What makes this different is the separation of compute and storage, which allows SurrealDB to scale horizontally to a level other databases can’t. With SurrealDB 3.2, Agent Memory, and SurrealDS, SurrealDB becomes the complete context layer for AI systems, where storage actively participates in reasoning, rather than simply retrieving data.
Building An Ambitious Technical Product
When asked about challenges in the sector and how SurrealDB has addressed them, Hitchcock noted:
We’re producing a highly technical product, and there’s a lot to build. And it’s a very ambitious product that requires a lot of investment, both in terms of time and finance.
But that ambition is paying off, as it positions us very well for the enterprises that seek it and need it. We always knew that our sights were well placed.
Technology Evolution
When asked how the company’s technology has evolved since launching, Hitchcock explained:
Technically, the product hasn’t evolved in terms of underlying principles and design. But how it’s used, and the layers around it, have evolved considerably.
We see changes in development patterns and workflows, and in the wider ecosystem, which is rapidly evolving. We’re still building a multi-model database that’s scalable, and are now very much focused on large-scale enterprise deployments, which increasingly need what we have to offer.
Major Company Milestones
When asked about some of the company’s most significant milestones, Hitchcock said:
Our initial launch, and raising our Seed round, followed by our Series A were important moments. Then, major technical milestones were the releases of 3.0 earlier this year, Agent Memory (soon to reach GA), and SurrealDS. But every stage is a major milestone for an early-stage company.
Customer Success Stories
When asked to share specific customer success stories, Hitchcock highlighted:
SurrealDB is used by companies including Samsung Ads, Tencent, Verizon, and Nvidia. It is designed for enterprise organizations with clear native AI use cases, and AI-native startups with heavy use of complex knowledge graph data across sectors such as defense, healthcare, retail, ecommerce, banking, telecommunications, and research.
Three examples illustrate how it is being used in practice:
Samsung: Unlocking Insights With Knowledge Graphs
SurrealDB’s multi-model engine helps Samsung Ads build dynamic, real-time knowledge graphs for smarter campaign execution. They do this by unifying content, user, and device graphs inside a single, high-performance layer. Native vector search, live queries, and rich graph traversal allow engineers to build, test, and deploy bespoke audiences on the fly, collapsing three legacy data stores into one and slashing total cost of ownership.
This has led to a 25% increase in campaign ROI, reduced query times from hours to seconds, and cut operational costs by 30%. The unified data layer has also provided a more complete view of customers, enabling deeper personalization and more effective engagement.
Tencent: Unified Infrastructure Monitoring
Tencent uses SurrealDB to consolidate nine backend tools into one real-time monitoring platform. The company integrated SurrealDB to unify its infrastructure monitoring stack. By combining native graph capabilities with versioned data access and built-in analytics, the team replaced a fragmented toolchain with a single, scalable, real-time monitoring platform.
Before SurrealDB, the monitoring and analysis experience spanned a patchwork of systems: MySQL, Elasticsearch, VictoriaMetrics (Prometheus-compatible), MongoDB, Doris, Trino, RisingWave, Flink (batch and stream processing), and Dgraph.
This has significantly reduced system complexity for both end users and the platform team. With fewer tools to manage, operational overhead has decreased, making governance, upgrades, and maintenance more straightforward.
At the same time, graph-based modeling has made it easier to analyze processes and reconstruct incidents in real time, supporting more efficient monitoring and debugging workflows.
Verizon: AI Assistant Empowering 10,000 Technicians
Verizon uses SurrealDB to power a generative AI assistant for 10,000 field technicians, delivering instant access to documentation, outage updates, and workflows.
This has reduced average response times by 40%, enabling faster service restoration. Technicians are able to complete more jobs per day as less time is spent searching for information, while training costs have fallen by 50% through more efficient knowledge sharing which has also boosted competency.
Faster service and improved technician performance have also contributed to higher customer retention.
Funding
When asked about funding and revenue metrics, Hitchcock shared:
SurrealDB recently secured an additional $23 million in Series A funding, bringing the company’s total investment to date (including seed) to $44 million. This makes SurrealDB one of the best-funded, early-stage database companies in history.
Chalfen Ventures and Begin Capital joined existing investors FirstMark and Georgian in this Series A extension, bringing the series total to $38 million.
Market Opportunity
When discussing the total addressable market SurrealDB is pursuing, Hitchcock said:
The sky’s the limit. The very largest enterprises are seeking us out, and we’re happy to offer them our expertise.
Competitive Differentiation
When asked what differentiates SurrealDB from its competition, Hitchcock emphasized:
Most organizations rely on multiple databases, one for relational data, another for documents, another for graphs, and so on. This works, but it often comes with trade-offs. Data becomes fragmented, systems need to be stitched together with APIs and pipelines, and maintaining consistency and context across them becomes increasingly complex as applications scale.
We take a different approach by bringing all of these data models together into a single system, supporting relational, document, graph, time-series, vector, search, geospatial, and key-value data with real-time capabilities built in.
At version 3.2, the platform moves beyond simply storing data to acting as a foundation for AI systems. It introduces first-class agent memory directly within the database, allowing models to run alongside the data, keep context synchronized, and simplify application logic.
This makes it particularly well suited to use cases where traditional architectures start to break down, for example, AI agents, knowledge graphs, and real-time systems that depend on constantly evolving relationships between data.
In these environments, managing multiple specialized databases can slow development and increase operational overhead, whereas a unified, context-aware data layer allows teams to move faster and build more capable systems.
Future Goals
When discussing the company’s future goals, Hitchcock explained:
The additional $23 million Series A funding gives us the ability to move faster and invest more deeply across product engineering, go-to-market, and customer success.
It lets us scale the team and the platform in parallel, shipping more capability, hardening reliability and security, and supporting larger deployments. In short, it accelerates our path from rapid adoption to durable, global scale.
Broadly, our innovation strategy is focused on three areas. Firstly, there’s a clear focus on driving production maturity at scale, proving value within the largest and most complex use cases.
Secondly, we’re expanding the platform so teams need fewer moving parts, while improving the overall developer experience.
Thirdly, as more organizations deploy AI in production, we’re investing in capabilities that make it easier to deploy and scale AI-powered applications and agentic workflows.
This spans everything from performance and reliability to tooling, observability, and secure deployment patterns, alongside deeper integrations with the platforms, frameworks, and tools teams already use.
Ultimately, it’s all about simplification, making systems faster to build, easier to run, and simpler to scale.
The Market Problem SurrealDB Addresses
When invited to discuss another topic, Hitchcock explained:
There’s a significant shift happening in AI, from theory to real-world implementation. While compute and model providers (LLMs) have received most of the attention, the data stack has become the critical bottleneck. Increasingly, AI projects are stalling not because the models aren’t capable, but because the underlying data infrastructure isn’t fit for purpose.
Research reflects this. A report from RAND highlights that organizations radically underestimate the data quality, lineage, access control, and deployment scaffolding needed to make AI reliable.
Gartner predicts that over 40% of agentic AI projects will be canceled by 2027, citing rising costs, governance challenges, and lack of clear ROI.
Similarly, MIT has found that the vast majority (95%) of GenAI pilots fail to reach production, with success depending heavily on workflow integration, domain specificity, and vendor-led solutions that scale where others stall.
At the core of this is a structural issue. Traditional databases were not built for AI. They were designed for transactional systems and static applications, not for dynamic, context-aware systems that need to reason across large volumes of interconnected data.
AI systems, particularly agentic AI, require a unified, consistent view of state, where context, relationships, and memory are maintained and updated in real time.
This is where AI agents fall short. While they can analyze data and generate responses, they often lack the memory and contextual understanding needed to make reliable decisions.
Traditional databases are not built for AI
AI systems require data to be modeled and stored in a way that’s optimized for LLMs. They need a data platform that makes unprecedentedly large-scale contextual information available to agentic systems, in a way that is synchronized across data sources, fast, and secure.
AI Agents have a memory problem
Agents may be able to analyze datasets and provide an answer based on what they see, but they lack the context to make proper sense of it. They lack the memory to be able to make relationship- and context-aware decisions. Here’s a brilliant example of when AI agents go spectacularly wrong.
Remember when Anthropic’s Claude ran a vending machine in the WSJ newsroom and gave away a free PlayStation. It also ordered a live fish, offered to buy stun guns, pepper spray, cigarettes, and underwear.
This was a very small, early experiment to see whether AI Agents could deliver a basic service, and it failed because its context and priorities were unstable. It’s a perfect example of how insufficient state and context memory can lead to direct financial loss, even in a controlled experiment.
Imagine this on a massive scale, in production across estates of devices; the costs would be unimaginable. SurrealDB is designed to give agents the memory and context they need.