TELUS Digital is a global technology company providing AI data solutions and services that support the development of generative AI, physical AI, robotics, and automotive systems for enterprise customers and frontier AI laboratories. Pulse 2.0 interviewed TELUS Digital VP of AI Growth & Solutions Sce Pike to learn more about her background, the challenges of collecting physical-world training data, robotics safety, data standardization, and the technologies needed to bring intelligent robots into everyday environments.
Sce Pike’s Background
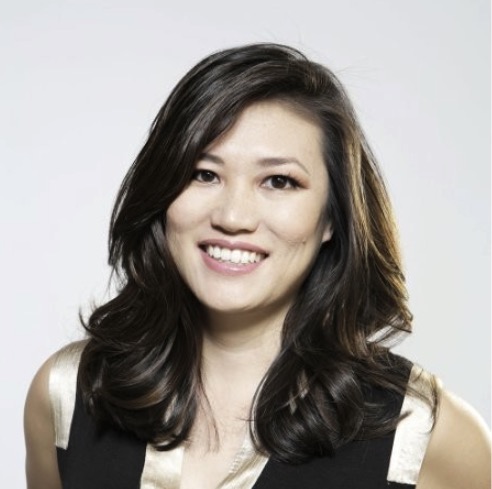
When asked about her professional background, Pike shared:
I’m a three-time founder, and I’ve spent more than 20 years building AI-enabled products, mostly where hardware, software and data meet. Early in my career, I worked at companies including Qualcomm, Palm, and Amp’d Mobile. I then co-founded Citizen, where I was Chief Experience Officer, and the company was later acquired by Ernst & Young.
After Citizen, I founded and was the CEO of IOTAS in Portland, a smart apartment platform that let property developers install connected outlets, switches, thermostats, door locks, and sensors before residents moved in. TELUS Ventures was one of our Series A investors, and ADT acquired the company in 2022.
Running IOTAS meant working with sensor data from real homes every day. It taught me how messy real-world data is and how much work it takes to make it usable, which is the same problem physical AI faces today at a much larger scale.
Sce Pike’s Role At TELUS Digital And The Shift Toward Physical AI
Discussing her responsibilities at TELUS Digital and how her work has evolved as the AI industry increasingly focuses on robotics and physical-world applications, Pike noted:
I joined TELUS Digital in 2025 as Vice President (VP) of Generative AI, and today I’m VP of AI Growth & Solutions. My work centers on helping companies building AI models figure out what data they need and how to get it at the quality their models require. When I started, most of that work involved large language models. More of my time now goes to physical AI, meaning robots and other systems that have to see, move and act in the real world.
That shift has evolved my role, because with language models, the raw material already existed online, and the work was in refining it. For physical AI, most of the data has to be captured from scratch by recording people and robots doing real tasks in real places.
TELUS Digital builds training data across physical AI and robotics, as well as generative AI and automotive, for frontier labs and enterprise AI teams. We don’t own AI models or robotics hardware, so we can work across companies without being tied to any one company’s proprietary format.
That independence is also why I spend a lot of time on standards, including the Robotics Data Standard Consortium we’re launching to help the industry agree on how this data should be captured and validated.
Challenges In Collecting Physical AI And Robotics Training Data
When asked why physical-world data presents challenges that large language models did not face, Pike emphasized the difficulty of collecting sufficient real-world training examples and ensuring responsible AI development:
Large language models (LLMs) were trained by scraping text from the internet. But physical AI has to build its data from scratch, through real-world actions.
In order for a robot to learn something like how to fold laundry or pick items off a shelf, it requires footage of those tasks being done in real spaces. Some of that footage comes from people wearing cameras while they do everyday tasks. It also comes from teleoperation, where a person remotely controls a robot through a task while the robot records what it sees and how it moves, giving the model examples of the task done correctly.
What makes this type of data collection so challenging is scale because physical AI data has to be recorded one task at a time. Supply of this data can only grow as fast as companies can add people, hardware and locations to collect it.
Ken Goldberg, the William S. Floyd Distinguished Chair of Engineering at UC Berkeley, put the size of this challenge in perspective in a 2025 Science Robotics editorial. He measures data in time. The text and images behind today’s vision language models, which learn from both, would take about 100,000 years to read and view continuously. The largest reported collection of data from people remotely operating robots only adds up to about one year of recording. Closing that massive gap means recording enormous amounts of real activity across many people and robots.
Staging and recording real-world actions requires people, equipment and quality checks in every location, and video costs more than text to store and process. That reality is shaping how robots get built. No single company can generate the amount of data physical AI needs on its own, so even the largest players end up depending on outside and pooled data.
Teams are also mixing sources, combining footage of people doing tasks with teleoperation data and simulation. Simulation helps in some areas, but Goldberg’s view, and my own, is that it remains unreliable for tasks that involve handling objects, which is one reason real-world data matters so much.
One more thing that I would like to emphasize on this topic is around Responsible AI. The robotics industry is actively creating this training data through assigned tasks to everyday collectors in the home and work environment. The companies driving this collection can easily choose what to train or not train their robotic models on.
For example, we would exclude any videos where an animal got intentionally harmed to finish the assigned task or anything that shows harm to humans or other living creatures.
LLMs ingested the entirety of the internet, the good and the bad, and there is a lot of debate now about the safety of these models and the backward engineering of constitutions and guardrails. We can, as an industry, actively choose to train physical AI models on good data where the “good” is for the betterment of humanity and our ecosystem.
How Fragmented Training Data Affects Robot Performance
Addressing the inconsistent hardware, imaging conditions, sensor placements, and annotation methods used by robotics companies, Pike identified several problems that can undermine model reliability:
The core problem is that a robot’s model learns the world through whatever lens collects its data, and right now, every company builds a different lens. When cameras, resolutions, lighting setups, sensor placements, and annotation conventions all vary, you end up with datasets that look like they describe the same task but are not actually comparable or combinable.
I see potentially three different issues:
First, the data cannot be pooled. A grasping dataset from one lab, recorded with a wrist camera at one frame rate and labeled with one taxonomy, can’t simply be merged with another lab’s dataset. Teams spend a huge share of their time on conversion, recalibration, and relabeling instead of improving models. That is why the field has so little shared data compared with language or vision, where web-scale corpora made rapid progress possible.
Second, models overfit to the collection setup rather than the task. If a policy is trained mostly on footage from one camera angle under bright warehouse lighting, it quietly learns those conditions as part of the task. Move the camera a few centimeters, dim the lights, or swap in a different gripper, and performance can drop sharply. This is the gap between a strong lab demo and a robot that works on a different shop floor.
Third, inconsistent annotation introduces noise you can’t see. If one team labels a successful grasp by contact and another by lift-off, or they define object categories differently, the model receives conflicting signals about what success means. That shows up as unpredictable behavior at the edges: hesitation, failed handoffs, or confident mistakes. It also makes benchmarking unreliable, because two companies can report results that cannot be fairly compared.
In real-world terms, this fragmentation shows up as brittleness. Robots perform well in conditions that resemble their training data and degrade in the messy variation of actual homes, factories, and streets. It also raises costs and slows safety validation, since regulators and customers can’t easily verify performance across environments when there’s no common yardstick.
Fragmentation in data collection can also drive up cost. An eight-hour collection session typically yields about two and a half to three usable hours, which means roughly two-thirds of the session doesn’t produce footage a model can learn from.
All of that footage gets uploaded, stored and processed before anyone can judge whether it’s usable, and teams often can’t tell until the data has been run through a model and benchmarked. By then the storage and compute have been spent, and the team may have to collect the data again.
The way forward is shared standards: common conventions for sensor calibration and metadata, consistent annotation schemas, and documented provenance so datasets can be combined and audited. Deliberate diversity matters too. The goal is not to make everyone collect data identically, but to make differences explicit and machine-readable, so models can learn from many sources and generalize.
That is the same shift that let other areas of AI scale, and robotics needs it to move from impressive demos to dependable deployment.
Establishing AI Safety And Data Standards For Robotics
When asked which robotics safety and data standards should be prioritized, and what lessons the industry could learn from aviation, automotive, healthcare, and other regulated sectors, Pike outlined a framework centered on governance, consent, traceability, and collaboration:
Our customers ask for consent from the collectors and all personally identifiable information to be removed. This is where the safety standards should start around data governance and provenance.
Every data point should carry a record of who collected it, where, under what agreement, and with what permissions. Models should be able to trace failures back to a specific gap in what the model was trained on.
They should also require documentation of edge cases and failure modes alongside successful task completions, since safety problems usually trace back to situations that were never represented in training.
These models are trained on footage from people’s homes and workplaces, so informed consent, privacy, and clear data controller and processor roles need to be built in from the start, not added after a complaint.
As I mentioned before, we need content safety standards for training data. This is where robotics has an opportunity that LLMs did not.
The companies directing this collection are assigning tasks to everyday collectors in homes and workplaces, so we choose what the data contains. We can set a clear rule that footage showing intentional harm to a person, an animal, or any living creature is excluded, including cases where harm happened in the course of finishing the assigned task.
In physical AI, we can curate at the source and decide that the behaviors a robot learns from are ones that benefit people and the ecosystem they share. Preventing a bad habit is much easier than unlearning one, especially when the model has a body and acts in the physical world.
On lessons from other industries, there are several good ones. Aviation built a culture of shared, non-punitive incident reporting, so one airline’s near miss improves safety for everyone. Robotics needs the equivalent.
Automotive developed functional safety standards and common autonomy levels that gave regulators, manufacturers, and the public a shared vocabulary. Healthcare and clinical research established consent, ethics review, and privacy rules for working with human data, which maps directly to collecting data in people’s homes.
Food and pharmaceuticals use traceability, so you can follow a product back to its source. Dataset lineage should work the same way. Robotics is early enough that we can build safety, consent, and quality into the foundation, and that will make the technology both more trustworthy and more useful.
Standards like these are more likely to stick when they’re shaped by a broad group of companies, rather than one company with its own hardware or format to protect.
That’s the idea behind the Robotics Data Standard Consortium, which my company, TELUS Digital, is launching to bring together hardware manufacturers, hyperscalers and academic institutions to define common use cases, hardware and capture standards, and industry benchmarks.
We want the standards to cover the full data lifecycle, including how data is captured, annotated, structured for training and benchmarked for quality, so that a dataset built to them works across labs and platforms.
Evaluating Physical AI Systems In Real-World Environments
Discussing how companies should validate robots before deploying them in hospitals, warehouses, factories, and homes, Pike stressed the importance of testing unfamiliar conditions and linking performance failures back to training data:
Companies should confirm that a robot can handle its real working environment before it’s deployed, rather than finding out through trial and error.
That process starts with the training data, by checking that it actually covers the conditions the robot will face when it’s put to use. If a robot is trained only in clean, ideal conditions, it will behave unpredictably the first time it encounters a messier space. So diversity in tasks and environments matters for safety just as much as for performance.
Testing should include conditions the robot never saw in training, such as clutter, low light, different surfaces and unfamiliar layouts.
If a robot is trained mostly in mild, dry places, it will eventually meet precipitation, ice and buildings laid out differently, so it needs to be able to handle that safely.
Companies should also benchmark against the specific environment where the robot will work, since a hospital corridor and a family kitchen involve different people, objects and risks.
Staged rollouts help with this, where you start with limited tasks and human oversight, and gradually increase challenges.
If a robot fails in the field, the team should be able to trace that failure back to a specific gap in its training data and collect what’s missing.
And that only works if the data was documented and validated consistently from the start, which is another reason provenance needs to be part of any data collection standard.
The Future Of Physical AI And Robotics Over The Next Three To Five Years
Looking ahead three to five years, Pike discussed the technological advances, shared infrastructure, and industry standards she believes will be necessary for physical AI to become reliable enough for widespread adoption:
Over the next few years, the advances in data will matter just as much as the models. The industry needs significantly more real-world data, captured across many more environments, along with better tools for checking the data’s quality close to the point of collection.
Right now, teams often discover bad data only after it has been stored, processed and run through a model. But, shared infrastructure is starting to help.
NVIDIA’s Physical AI Data Factory Blueprint, for example, gives the industry an open architecture for generating, augmenting and evaluating training data.
However, a shared pipeline is different from a shared standard for what counts as trustworthy data, and that question is still open across companies.
I expect practical industry standards to be established first, starting with data formats and quality benchmarks, and then formal processes to catch up behind them.
For example, a working group under ISO’s robotics technical committee is developing general requirements for humanoid robot datasets, though the standard is still in draft.
Timing is really important. Capital and deployment are moving quickly, and no single company has emerged as the clear leader in physical AI the way one did in earlier AI waves, so a collective effort is still possible.
If one company comes to dominate physical AI, building the leading robots and controlling most of the data used to train them, its own data formats and quality rules will likely become the default, and everyone else will have to adapt to them.
Standards set that way tend to reflect one company’s hardware and priorities, rather than what works across the industry. That’s why the window for building shared standards together is now, while the field is still open.
The incentives for the industry to agree on data standards are strong because this will let a company combine data from multiple collection partners and reuse it across model generations without reformatting everything each time.
Companies can standardize that foundation and still compete on the models and policies they build on top of it.
And as regulated and risk-averse industries start bringing robots into their operations, they’ll want assurance that the training data meets a recognized safety bar. That trust is essential to move physical AI from specialized deployments into everyday life.